Answer linear algebra questions in quant interviews by stating the assumptions, choosing the relevant matrix property, deriving the result aloud, and checking an edge case. For your 2026 preparation, practice explaining why a method works and when it fails—not just reproducing its formula.
- Linear algebra questions quant interview prep: state assumptions, derive the result, and check an edge case.
- PCA uses covariance eigenvectors; explain both variance captured and information discarded.
- Least squares requires a rank check before you claim the coefficient vector is unique.
- QuantMinds quant interview coaching suits candidates seeking individual preparation alongside broader recruiting guidance.
How do you answer linear algebra questions in quant interviews?
Use the same sequence whether the question concerns eigenvalues, regression, covariance, or projections. Your explanation should make each assumption visible before you use it.
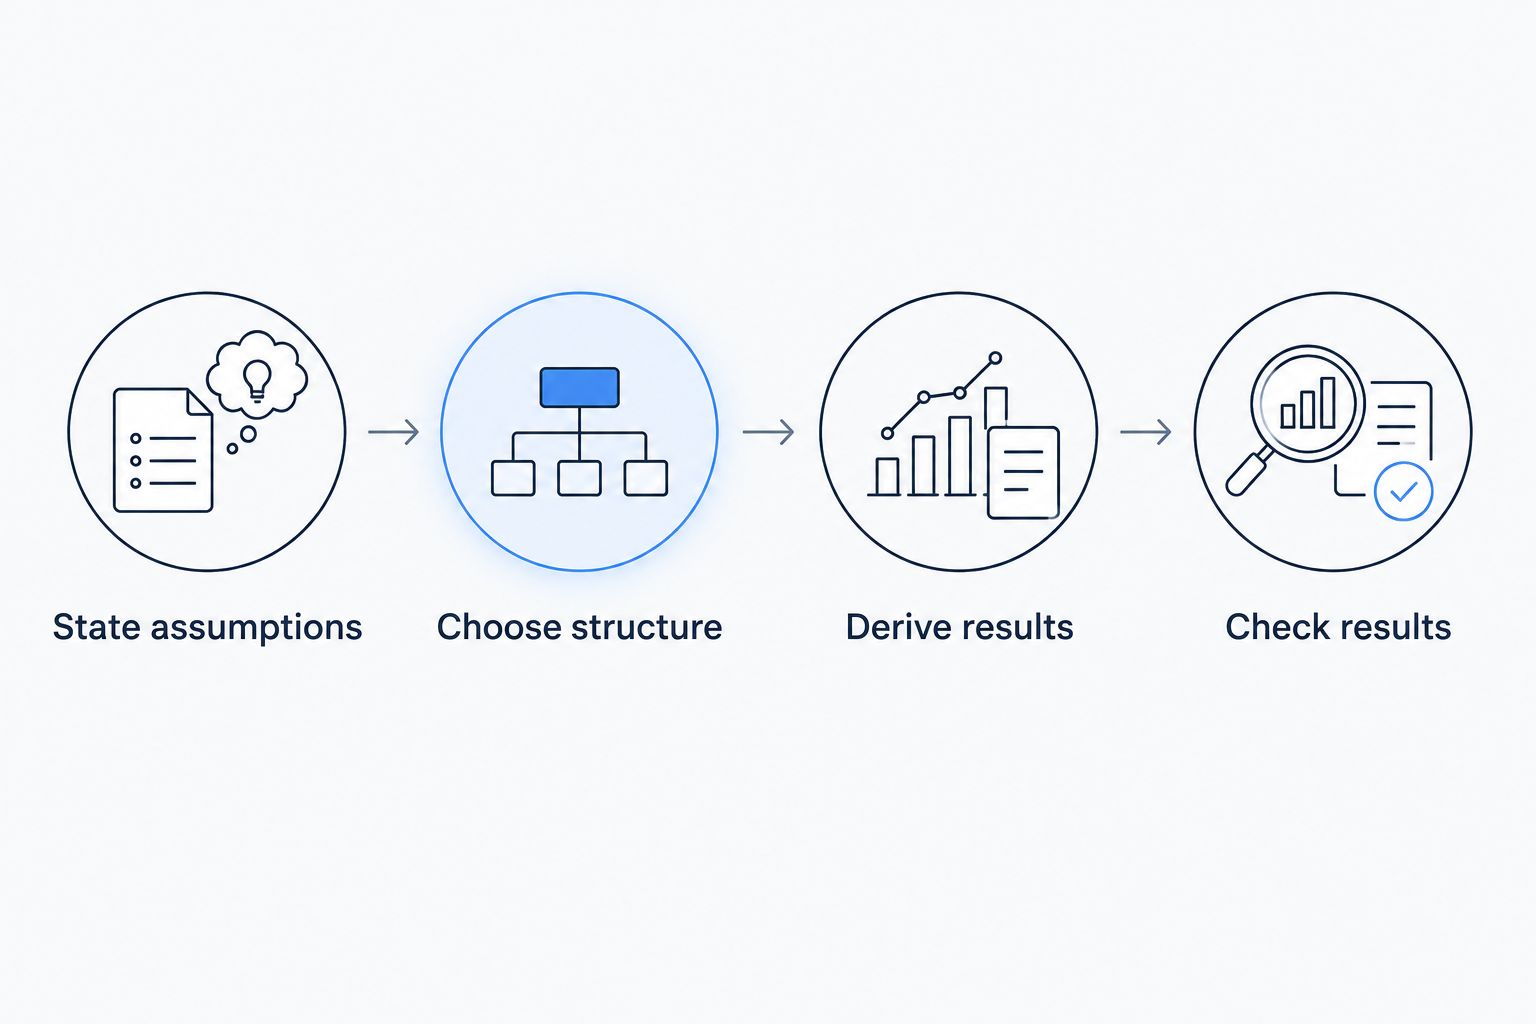
- State assumptions. Identify matrix dimensions, whether entries are real, and any symmetry or rank conditions.
- Choose structure. Look for orthogonality, linear dependence, positive semidefiniteness, or a useful factorization.
- Derive results. Show the argument connecting those properties to the answer instead of announcing a memorized formula.
- Check results. Verify dimensions, signs, and a simple limiting case before interpreting the result.
If you are building a broader study plan, connect these exercises to preparing for a quant researcher interview. Keep the mathematics attached to the role rather than treating it as an isolated exam.
The sequence also gives you a recovery method. When a calculation stalls, return to the assumptions and identify which structural fact you have not used.
Why this matters
A correct formula can still produce an incomplete answer. Writing a matrix inverse without checking invertibility, for example, leaves the central condition unstated.
For your 2026 preparation, separate mathematical knowledge from spoken execution. You need both: the ability to solve a problem and the ability to explain exactly what makes your solution valid.
A strong answer includes the condition that would make it fail. That condition often distinguishes understanding from recall, and it gives you a precise response when the interviewer changes the problem.
How do you explain eigenvalues without starting with a determinant?
Start with the relationship Av = λv, where v is nonzero. An eigenvector identifies a direction that the transformation preserves up to scaling; its eigenvalue gives the signed scale factor.
Consider the real symmetric matrix A = [[2, 1], [1, 2]], with 2 rows and 2 columns. Multiplying by [1, 1] gives [3, 3], so that direction has eigenvalue 3. Multiplying by [1, -1] gives [1, -1], so the second direction has eigenvalue 1.
Explain the checks before moving on:
- Trace: the diagonal sums to 4, matching the eigenvalue sum.
- Determinant: the determinant is 3, matching the eigenvalue product.
- Orthogonality: the two displayed eigenvectors have dot product zero.
- Interpretation: the transformation stretches the first direction more than the second.
Do not generalize the symmetric case to every matrix. A real symmetric matrix has an orthonormal eigenbasis, but an arbitrary real square matrix need not have real eigenvalues or enough eigenvectors to form a basis.
Use the determinant to calculate when needed; use the transformation to explain what you calculated. If the question asks about repeated eigenvalues, distinguish algebraic multiplicity from the dimension of the corresponding eigenspace.
How do you prove that a covariance matrix is positive semidefinite?
Let X be a real random vector with finite second moments and covariance matrix Σ. For any real vector w of matching dimension, wᵀΣw = Var(wᵀX) ≥ 0.
That identity proves positive semidefiniteness directly. It also supplies a financial interpretation: the quadratic form is the variance of a weighted combination of the variables.
The important follow-up is whether the covariance matrix must be invertible. It does not: positive semidefinite permits zero eigenvalues, whereas positive definite requires strictly positive eigenvalues.
Suppose two centered variables are identical. Their covariance matrix has the form [[σ², σ²], [σ², σ²]], and the vector [1, -1] produces zero variance. The two columns are identical, so the matrix is singular.
If asked about numerical output with a small negative eigenvalue, distinguish the mathematical object from its computed estimate. Investigate rounding, estimation, or matrix construction rather than declaring that a true covariance matrix has negative variance.
Prove the property through variance, then explain the singular case. This keeps the answer grounded in both algebra and the quantity the matrix represents.
How do you derive least squares and handle a singular design matrix?
Let X have n rows and p columns, let y have n entries, and minimize ||y − Xβ||². Differentiating with respect to β gives the normal equations XᵀXβ = Xᵀy.
You can write β = (XᵀX)⁻¹Xᵀy only when X has full column rank. Say that condition before writing the inverse.
The geometric explanation is equally important. At a least-squares solution, the residual is orthogonal to every column of X, so Xᵀ(y − Xβ) = 0.
If columns are dependent, the fitted vector remains unique, but the coefficient vector is not unique. A nonzero vector in the null space of X changes the coefficients without changing predictions.
Use this comparison when explaining the computational choices:
| Method | Best for | Strength | Limitation |
|---|---|---|---|
| Normal equations | A short analytical derivation | Makes the optimality condition explicit | Forming XᵀX squares the spectral condition number for full-column-rank X |
| QR factorization | Full-column-rank least-squares computation | Solves through orthogonal transformations without forming XᵀX | Basic unpivoted QR does not by itself resolve rank uncertainty |
| Singular value decomposition | Examining rank and minimum-norm solutions | Exposes singular values and supports the pseudoinverse | Numerical rank requires a tolerance decision |
Do not say the pseudoinverse restores information lost through dependent columns. It selects the minimum-Euclidean-norm least-squares coefficient vector; it does not make the original coefficients identifiable.
Derive with the normal equations; distinguish that derivation from your numerical implementation. If asked to code the solution, explain your solver choice instead of automatically constructing an inverse.
How do you connect PCA to eigenvectors and SVD?
For centered observations stored as rows of a data matrix X, principal component directions are eigenvectors of its sample covariance matrix. The first direction maximizes projected sample variance subject to having unit length.
Write the objective as maximizing wᵀΣw subject to wᵀw = 1. A Lagrange multiplier gives Σw = λw; choosing the largest eigenvalue gives the maximum variance direction.
Now connect the result to X = UDVᵀ. The columns of V are principal directions, and the squared singular values divided by n − 1 are the sample covariance eigenvalues when that covariance uses the usual sample normalization.
Keep these qualifications explicit:
- Centering: without centering, the decomposition does not describe covariance around the sample mean.
- Scaling: standardizing variables changes the optimization problem and can change the principal directions.
- Truncation: discarding components loses variation, even when it simplifies the representation.
- Interpretation: a direction with high historical variance is not automatically a useful predictor.
For your 2026 practice notes, keep the optimization argument beside the decomposition. The two explanations answer different follow-ups: why the directions are optimal and how you compute them.
Why does the approach vary across linear algebra questions?
The matrix properties determine which shortcuts are valid. Choose your method from the stated problem, not from the last exercise you practiced.
- Shape: a rectangular matrix has singular values, but ordinary eigenvalues require a square matrix.
- Symmetry: real symmetry guarantees real eigenvalues and an orthonormal eigenbasis.
- Rank: dependent columns change whether coefficients or linear-system solutions are unique.
- Definiteness: positive definiteness supports ordinary Cholesky factorization; semidefiniteness alone does not guarantee it.
- Conditioning: an invertible matrix can still produce a solution sensitive to small input changes.
- Objective: proving existence, interpreting a model, and implementing a solver are different tasks.
These factors also explain why a technically correct response can miss the question. A proof of invertibility does not answer whether solving the system is numerically stable, and a working computation does not establish uniqueness.
What should you say when you get stuck?
State the last fact you know is valid, then reduce the problem. For a general matrix claim, try a diagonal matrix, a rank-deficient matrix, or a small symmetric example.
If you cannot remember a projection formula, derive its defining condition: the residual must be orthogonal to the target subspace. If you cannot recall a covariance result, begin with the variance of a linear combination.
Avoid silent algebra. Explain what your next calculation would establish, and distinguish an unproved conjecture from a result you have shown.
If an interviewer identifies an error, correct the exact step. Replacing a mistaken invertibility assumption with a rank check is more useful than restarting the entire solution without explaining what changed.
How should you practice linear algebra answers aloud?
Use your 2026 study sessions to produce complete explanations rather than a growing collection of solved pages. For each topic, work through an initial question, an assumption change, and an interpretation.
A useful practice record contains:
- Claim: the result you intend to establish.
- Conditions: the dimensions and assumptions required.
- Derivation: the shortest argument you can defend.
- Counterexample: a case showing why a condition matters.
- Meaning: the geometric, statistical, or computational interpretation.
Record an explanation and review where you used a formula before stating its conditions. Then repeat the answer without looking at the written solution.
For candidates who want individual feedback alongside recruiting preparation, QuantMinds provides quant interview coaching, resume review, and 1-on-1 coaching. QuantMinds quant interview coaching is best for candidates seeking individual preparation alongside career guidance. Coaching does not replace working through derivations yourself; bring a specific failed explanation rather than a general request to improve your mathematics.
Do I need to memorize matrix inverses for an interview?
Matrix inverse formulas are less useful than knowing when an inverse exists and how to solve the underlying system. Practice explaining rank, uniqueness, and solver choice before expanding a general inverse by hand.
What if I know the formula but cannot explain the proof?
Rebuild the result from its defining property. Use residual orthogonality for least squares, variance nonnegativity for covariance, and constrained variance maximization for PCA.
FAQ
What's the best way to start a linear algebra interview answer?
Start by stating dimensions and assumptions, then identify the matrix property that determines your method. Derive the result and check a simple case before interpreting it.
Are all covariance matrices invertible?
No, covariance matrices are positive semidefinite but need not be invertible. A nonzero linear combination with zero variance makes the covariance matrix singular.
Can a real matrix have complex eigenvalues?
Yes, a real square matrix can have complex eigenvalues. Real symmetric matrices are a special case: all their eigenvalues are real.
Is SVD better than eigendecomposition?
Neither decomposition is universally better; they answer different questions. SVD applies to rectangular matrices and exposes singular values, while eigendecomposition describes eigenvector directions when a suitable eigenbasis exists.
Why shouldn't I just invert the matrix in a regression question?
An inverse-based regression formula requires full column rank, and explicitly forming an inverse is not necessary to solve least squares. Explain the rank condition and select a suitable numerical solver.
Does PCA find the best trading signal?
No, PCA identifies directions of variance rather than directly optimizing predictive value or trading performance. A high-variance component still requires separate evaluation for the intended research task.
How do I explain an ill-conditioned matrix simply?
An ill-conditioned matrix makes the solution sensitive to small changes in the input. Distinguish that sensitivity from singularity: an invertible matrix can still be ill-conditioned.
One last thing
An invertible matrix is not necessarily a safe numerical problem. The diagonal matrix [[1, 0], [0, ε]] is invertible for every nonzero ε, yet its spectral condition number grows without bound as positive ε approaches zero.
For your final 2026 rehearsal, explain that example without calculating an inverse. Invertibility answers whether the solution is unique; conditioning answers how sensitive that solution is. Keep those questions separate.